Axelerated Solutions · shipped
Saudi-dialect speech-to-text
Whisper large-v3 fine-tuned for Saudi dialect, with an audio pipeline for WhatsApp and Asterisk calls, behind live transcripts and tool-using voice agents.
Problem
Contact centres in Saudi Arabia take most of their calls and voice notes in Saudi dialect, not Modern Standard Arabic. Off-the-shelf speech-to-text models are trained mostly on MSA and other dialects, so they drop or mangle exactly the words that matter: order numbers, product names, complaints. Without reliable transcripts there is no search, no analytics, and no voice agent that can act on what the customer said.
Constraints
- Dialect and code-switching: Saudi Arabic mixed with English product terms and numbers.
- Telephony audio: narrow-band Asterisk recordings and compressed WhatsApp voice notes, with noise and cross-talk.
- Data residency: government and enterprise clients, so audio and transcripts could not go to a third-party speech API.
- Real time: transcripts feed a live agent, so latency matters as much as accuracy.
Architecture
Diagram source (Mermaid)
flowchart TB
  wa[WhatsApp voice notes] --> prep[Resample · segment · label]
  ast[Asterisk call audio] --> prep
  prep --> model[Whisper large-v3 · fine-tuned for Saudi dialect]
  model --> live[Live transcript · agent tools]
  model --> cv[Customer Voice RAG pipeline]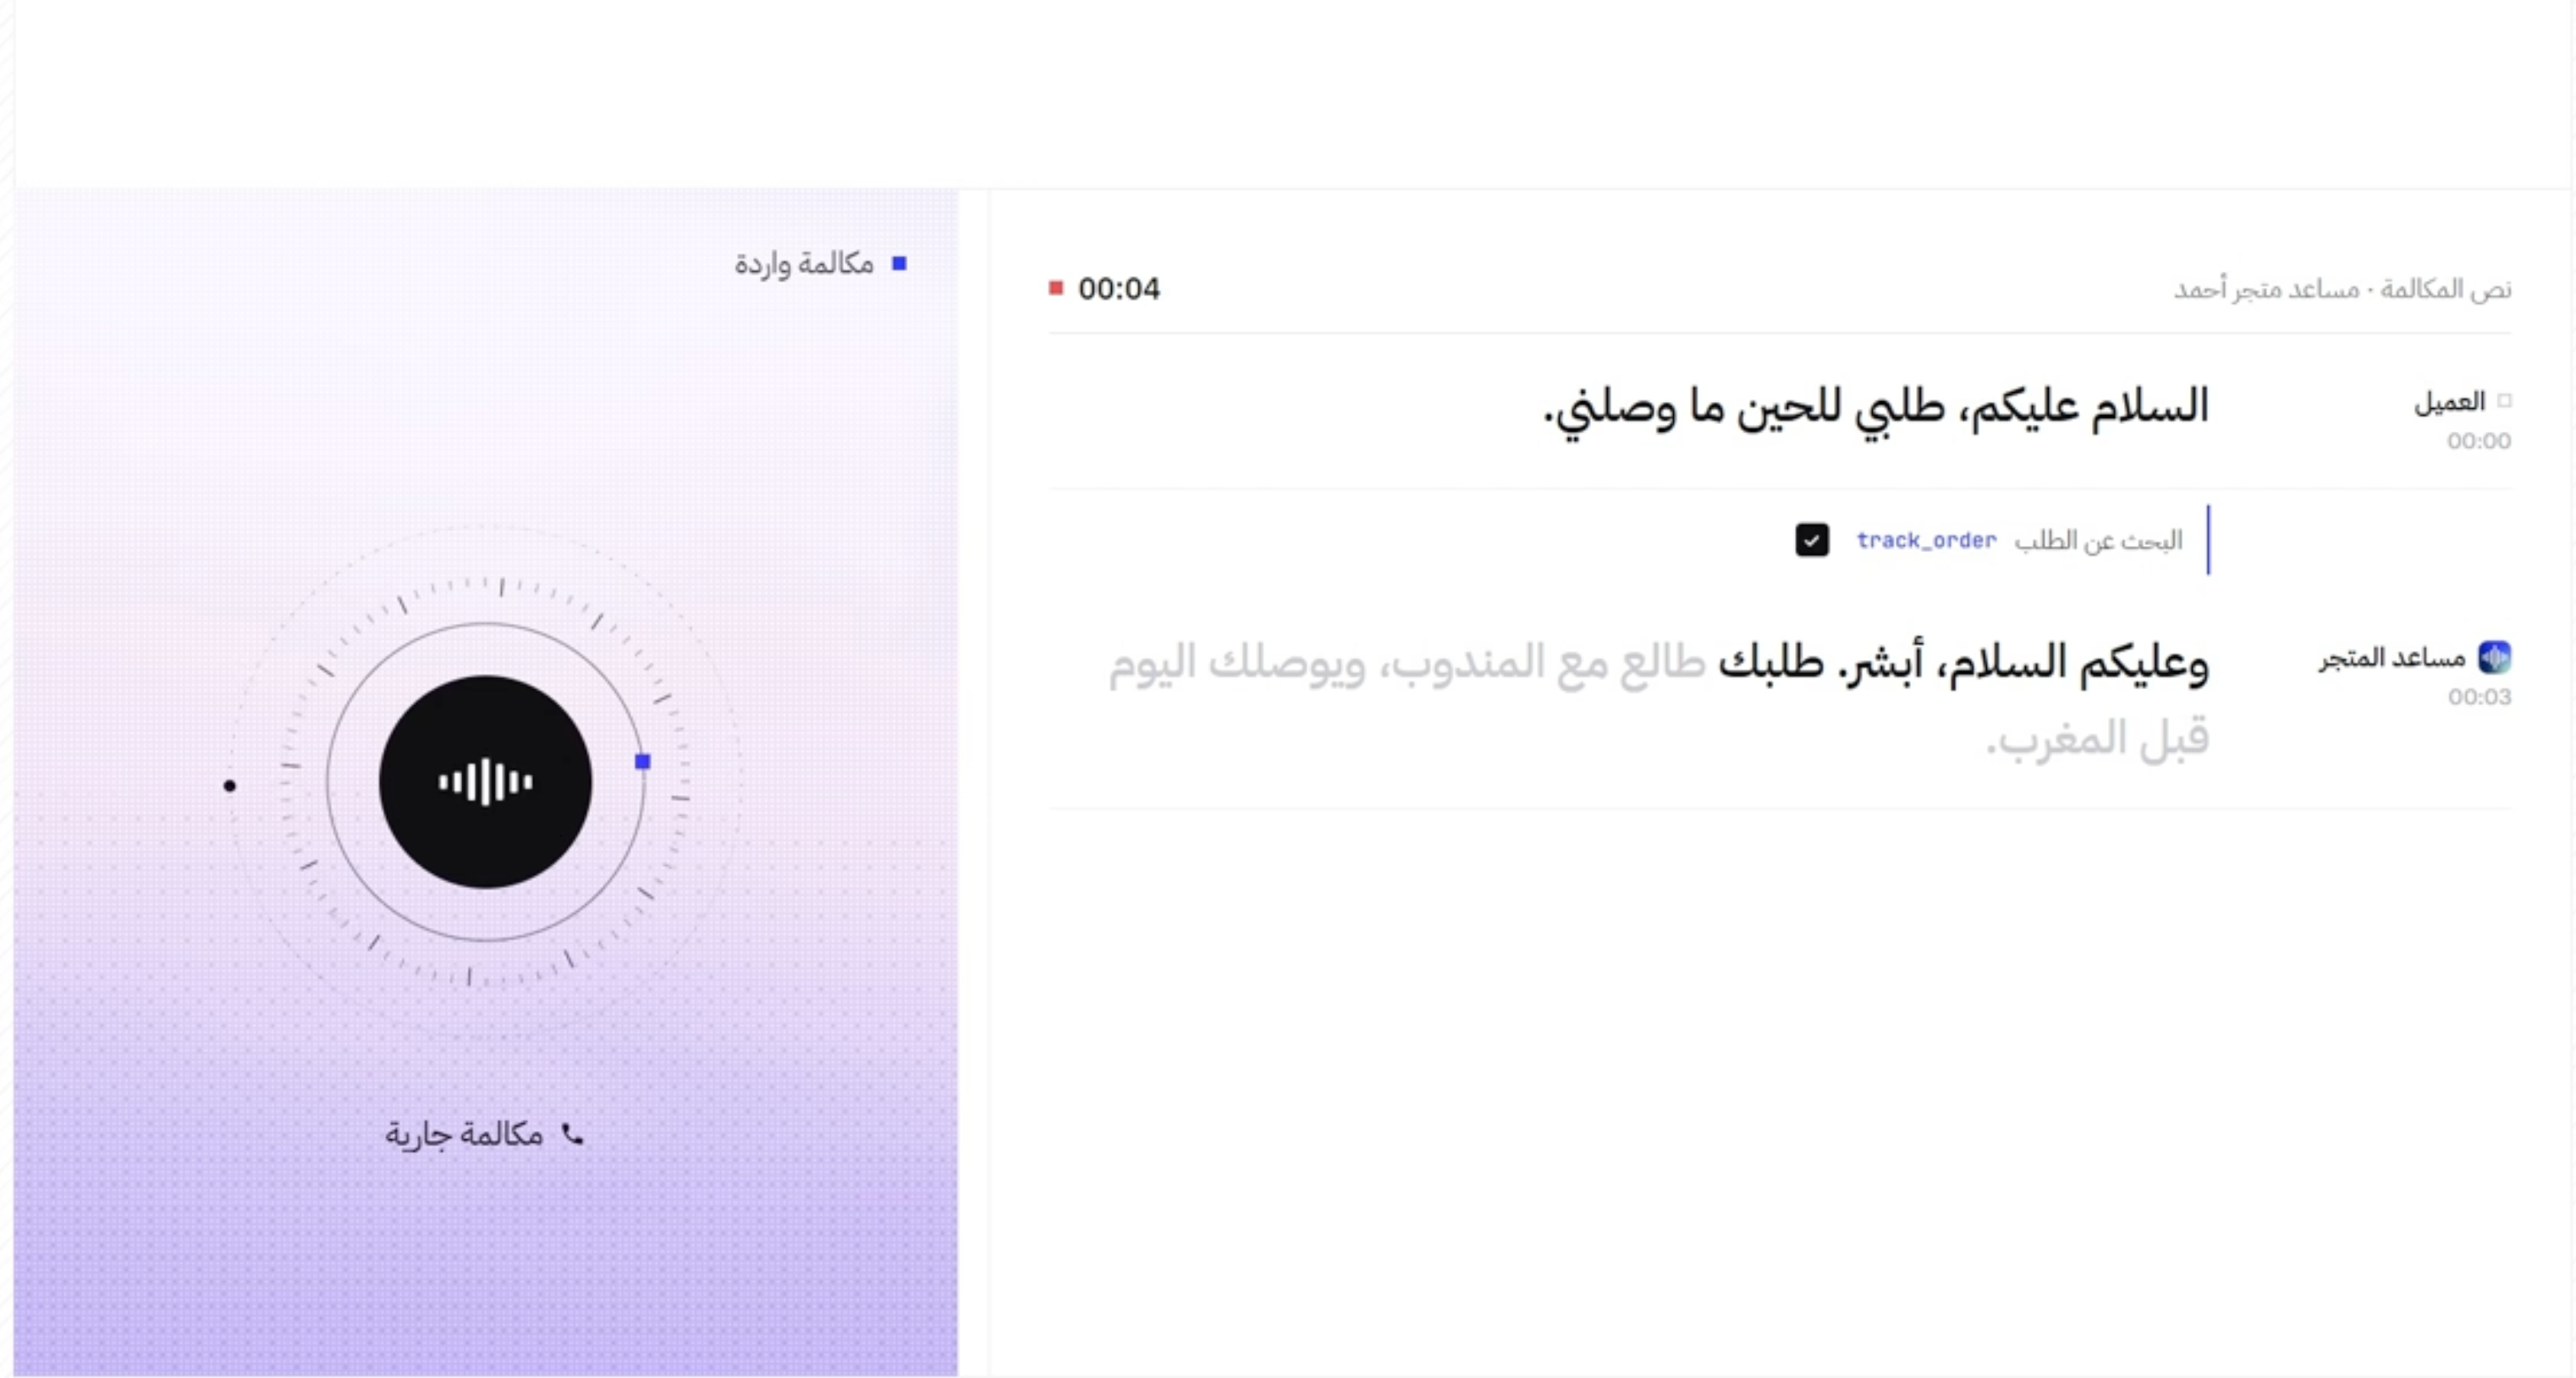
In the call above the customer says «طلبي للحين ما وصلني» (“my order still hasn’t reached me”). The transcript is reliable enough for the agent to call track_order mid-call and answer with the courier status.
Key decisions
- Fine-tune Whisper large-v3 rather than use a hosted speech API. Hosted APIs were weaker on Saudi dialect and would have sent client audio outside the deployment. Fine-tuning an open model kept audio in-house and let the vocabulary follow the clients’ domains.
- Invest in data preparation before training. Every source was normalised to the same format, split at speaker turns and labelled, so the model learned the dialect rather than the quirks of each channel.
- One model for live and offline use. The same fine-tuned model serves live transcripts for agents and batch transcripts for the Customer Voice pipeline, so improvements reach both.
Results
- Word error rate, base Whisper large-v3 → fine-tuned
- 40% → 15%
- Held-out evaluation set of Saudi-dialect calls and voice notes from callers not seen in training. An offline evaluation, not production traffic.
Stack and links
Deep dives
- Sowtek: VoIP, PBX processing and sentiment detection: Backend for Sowtek's call centre on Asterisk: PBX event processing, call recording pipelines and sentiment detection on transcribed calls.